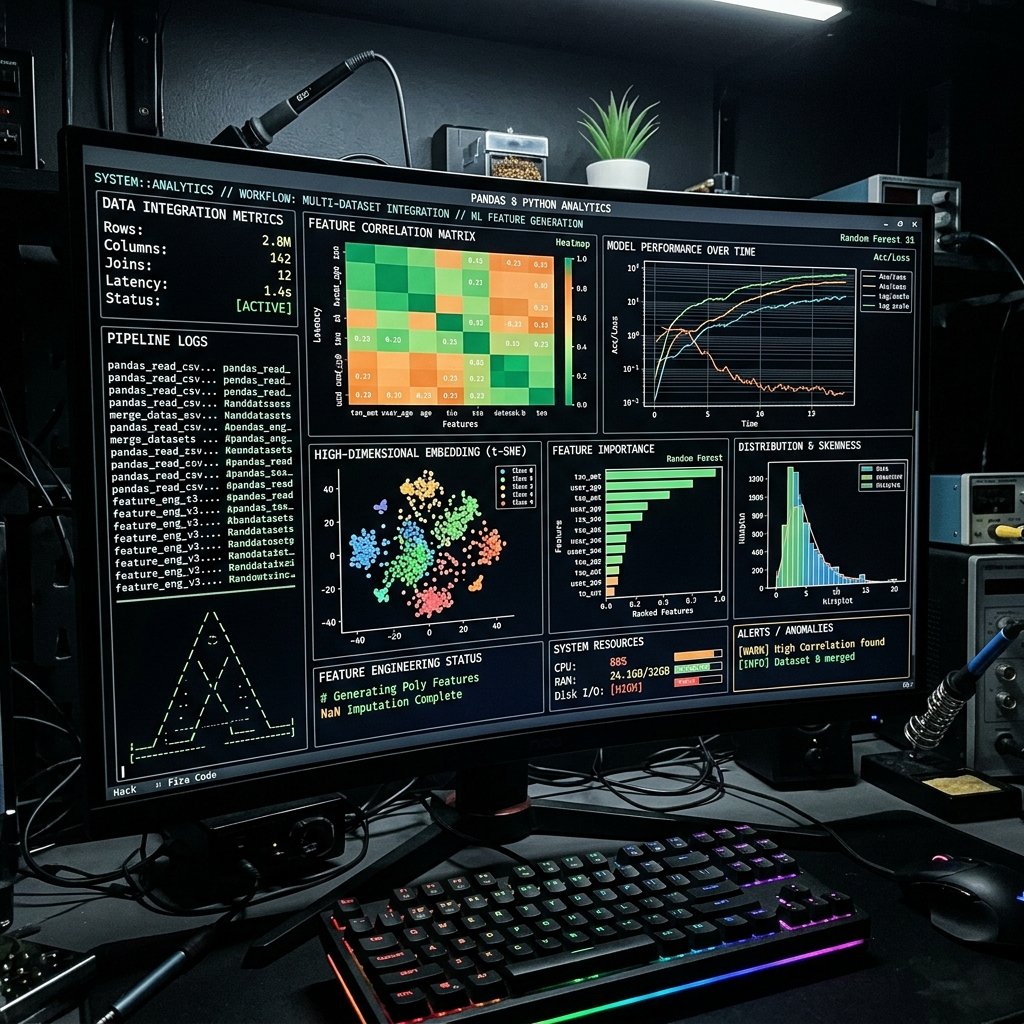
Multi-Dataset Analytics Core
The Architecture
Automated feature generation models designed to analyze massive real-world customer tables, implementing algorithmic corrections that lifted baseline classification performance by 12%.
This core was engineered during my ML Internship to clean, merge, and visualize complex datasets utilizing cutting-edge Python libraries, forming the foundation of a predictive machine learning pipeline.
Data Visualization
Translating thousands of rows of relational data into high-contrast Matplotlib visualizations to instantly identify correlation and outliers.
ETL Pipelines
Optimized Extract, Transform, Load (ETL) pipelines using Pandas and SQL queries to sanitize raw data before ML ingestion.
Click to expand evidence